If you make a constraint in Interface Builder. If you click a constraint that has already be selected. Normally you would be able to see the knobs for it in the Right panel. However, if you double click this constraint, a little window will open up that will also let you turn the knows. Good for if you don't want to open the Right panel.
Also if you press option when a view is selected it will show you the distance from its neighboring views. Yes, I realized that it isn't Auto layout per se, but it its somewhat related.
Sunday, June 28, 2015

Tuesday, June 23, 2015
Objective -c Tuple
Objective - c does not have native support for Tuples. However, in most cases an NSArray will suffice. The difference between a tuple and an array is mostly one of categorization. Tuples are for bundling things that don't have uniformity while Arrays are expected to have the same type. With that said, a Tuple can be implemented by using an Array, but with it's array features hidden away.
Below is my implantation for a Tuple by using Blocks and variadic function.
typedef id(^TupleType)(NSInteger);
TupleType Tuple(id obj, ...) NS_REQUIRES_NIL_TERMINATION;
TupleType Tuple(id obj, ...) {
va_list argList;
va_start(argList, obj);
NSMutableArray *mut = [NSMutableArray new];
for (; obj; obj = va_arg(argList, id)){
[mut addObject:obj];
}
va_end(argList);
return ^(NSInteger index){
return index >= mut.count ? nil : mut[index];
};
}
You can use it like this
TupleType t = Tuple([MYObj new], [MYObj new], [MYObj new], nil);
for (int i = 0; i < 3; ++i)
{
NSLog(@"%@", t(i));
}
Sunday, June 21, 2015
Adding a radial gradient
Have you used UIAlertController? Have you ever made your own? Well, I have. This blog will not be able how to make your own UIAlertController; instead, it will be about a little known detail that makes the UIAlertController look the way it does.
If you open up a UIAlertView (the predecessor to UIAlertController) in the View Debugging while you run your app, it will not appear. Therefore use UIAlertController and it will appear. Did you know that UIAlertControllers have a radial gradient above it? It is difficult to tell since the view debugging does NOT reveal this gradient. Instead it just says that the UIAlertController is White. But it is more than that. It is partially transparent and there is a Radial gradient which makes it look like there is a spot light on it. Very subtle yes I know.
But how do you do that? How do you make the radial gradient? The secret word is CGContextDrawRadialGradient
Take a look at my github project and see how I have used it with IBDesignables and IBInspectables. I used the IBInspectables to learn what each value of CGContextDrawRadialGradient actually does and ran it through IBDesignables to render it as I modify the values.
Friday, June 19, 2015
Codillity Tape equilibrium Solution in Python
The intuitive thing to do is to sum up the array ranges to calculate P of 1..N but that is inefficient.
Observations:
p0 = | (A[0]) - (A[1] + A[2]) |
p1 = | (A[0] + A[1]) - (A[2]) |
If we abstract a bit then we can put the sums into two sets. The left set can be sum1 and the right set can be sum2. For each p we essentially add on to set 1 and subtract from set2 the same number. This saves you from having to sum the array ranges more than you need to.
#solution in Python
import sys
def solution(A):
sum1 = 0
sum2 = sum(A)
diff = sys.maxint
for i in range(0, len(A) -1):
sum1 += A[i]
sum2 -= A[i]
_diff = abs(sum1 - sum2)
if (diff > _diff):
diff = _diff
return diff
https://codility.com/demo/results/demo73W5DE-WZP/
Sunday, June 14, 2015
C arrays and Objective-C ARC
I just converted a MRR (manual retain release) project into a ARC (automatic reference counting) project.
I use Xcode to help me convert the project super fast. However, I noticed that in some of my classes there were C arrays that contained NSObject instances. My first reaction was to say that C can not manage NSObjects, I mean how? It isn't like NSArray where if you deallocate the NSArray it would automatically remove its reference from each of its instance. A C array is a different beast and I could not fathom how it could "remove its reference".
So I skip it and told code to make that particular class MRR.
But curiosity got the best of me and I made a small project to see if the C array of NSObjects would deallocate with its parent class. In short? Yes. The C array deallocates along with its Parent.
Here is the code that I used to test this.
In the viewDidLoad method of dh123ViewController, I create 3 DHViews and add it to the views property. In the DHView I added an NSLog to the dealloc method so that I could see when it gets deallocated. When I dismiss dh123ViewController all three DHViews deallocate.
Therefore, you should use as many C array's as your heart desires!
I use Xcode to help me convert the project super fast. However, I noticed that in some of my classes there were C arrays that contained NSObject instances. My first reaction was to say that C can not manage NSObjects, I mean how? It isn't like NSArray where if you deallocate the NSArray it would automatically remove its reference from each of its instance. A C array is a different beast and I could not fathom how it could "remove its reference".
So I skip it and told code to make that particular class MRR.
But curiosity got the best of me and I made a small project to see if the C array of NSObjects would deallocate with its parent class. In short? Yes. The C array deallocates along with its Parent.
Here is the code that I used to test this.
@interface DHView : UIView
@end
@implementation DHView
- (void)dealloc {
NSLog(@"Dealloc: %@", self);
}
@end
@implementation dh123 {
DHView *views[3];
}
-(void)viewDidLoad {
[super viewDidLoad];
views[0] = [DHView new];
views[1] = [DHView new];
views[2] = [DHView new];
for (int i = 0; i < 3; ++i) {
NSLog(@"Create: %@\n", views[i]);
}
}
@end
Therefore, you should use as many C array's as your heart desires!
Sunday, May 31, 2015
How to Curry Functions in Objective-C
Calling a function is an all-or-nothing ordeal; You either call it or you don't. There is no in-between. Or is there?
In functional programming there is a concept of currying, which mean that you can partially apply a function. If you have 3 arguments, you can partially apply it by using only the first argument. The function would then return a partial function. It is only after applying the 2nd and 3rd arguments will you get the a complete return value.
This is not nearly syntactic sugar. You can pass around this partial function. It saves on code duplication. See the below example to see a C function as a curried function.
typeE(^(^(^arg1)(typeB))(typeC))(typeD) = day(@{@"å" : @5});
typeE(^(^arg2)(typeC))(typeD) = day(@{@"å" : @5})(256);
typeE(^arg3)(typeD) = day(@{@"å" : @5})(256)(3.14);
typeE arg4 = day(@{@"å" : @5})(256)(3.14)(@[@76]);
NSLog(@"%p", day);
NSLog(@"%@", arg1);
NSLog(@"%@", arg2);
NSLog(@"%@", arg3);
NSLog(@"%@", arg4);
The above is how you can curry a four argument function that returns a value of typeE.
The return type for the day function may look confusing, but its pattern is essentially just repeated over and over again. Conceivably you could create a macro or work some typedef magic. Nonetheless, the partial function works by returning blocks.
Here is another example where I use an objective-c method. I don't recommend it.
Before we end this i'd like to address the issue of type. Especially if you try to save the partial function into a variable. You can not cast it to type id. I mean you could, but you won't be able to call the parameters. You could however use "typeof()" to get the type. It does not appear to call the function twice so you are probably safe from calling something twice.
In functional programming there is a concept of currying, which mean that you can partially apply a function. If you have 3 arguments, you can partially apply it by using only the first argument. The function would then return a partial function. It is only after applying the 2nd and 3rd arguments will you get the a complete return value.
This is not nearly syntactic sugar. You can pass around this partial function. It saves on code duplication. See the below example to see a C function as a curried function.
typedef NSDictionary *typeA;
typedef int typeB;
typedef float typeC;
typedef NSArray *typeD;
typedef NSString *typeE;
typeE(^(^(^day(typeA A))(typeB B))(typeC C))(typeD D) {
return ^(typeB B) {
return ^(typeC C) {
return ^(typeD D) {
return (typeE)[NSString stringWithFormat:@"%@ %d %f %@", A, B, C, D];
};
};
};
}
...
NSLog(@"%@", day(@{})(99)(215.9)(@[@"bye", @"vanishment"])); // Example usage
typeE(^(^arg2)(typeC))(typeD) = day(@{@"å" : @5})(256);
typeE(^arg3)(typeD) = day(@{@"å" : @5})(256)(3.14);
typeE arg4 = day(@{@"å" : @5})(256)(3.14)(@[@76]);
NSLog(@"%@", arg1);
NSLog(@"%@", arg2);
NSLog(@"%@", arg3);
NSLog(@"%@", arg4);
2015-05-31 11:03:32.694 curry[2566:41971] 0x10a1bfa40
2015-05-31 11:03:32.696 curry[2566:41971] <__NSMallocBlock__: 0x7fa158c1ce60>
2015-05-31 11:03:32.696 curry[2566:41971] <__NSMallocBlock__: 0x7fa158c5e990>
2015-05-31 11:03:32.696 curry[2566:41971] <__NSMallocBlock__: 0x7fa158c13cf0>
2015-05-31 11:03:32.697 curry[2566:41971] {
"\U00e5" = 5;
} 256 3.140000 (
76
)
The above is how you can curry a four argument function that returns a value of typeE.
The return type for the day function may look confusing, but its pattern is essentially just repeated over and over again. Conceivably you could create a macro or work some typedef magic. Nonetheless, the partial function works by returning blocks.
Here is another example where I use an objective-c method. I don't recommend it.
typedef int type1;
typedef float type2;
typedef NSArray *type3;
typedef NSString *type4;
- (type4(^(^)(type2))(type3))day:(type1)day {
return ^(type2 deg) {
return ^(type3 arr) {
return (type4)[NSString stringWithFormat:@"%d %f %@", day, deg, arr];
};
};
}
Before we end this i'd like to address the issue of type. Especially if you try to save the partial function into a variable. You can not cast it to type id. I mean you could, but you won't be able to call the parameters. You could however use "typeof()" to get the type. It does not appear to call the function twice so you are probably safe from calling something twice.
Wednesday, June 18, 2014
uiimage to nsdata to nsstring to nsdata to uiimage
Why would you want to make these conversions?
nsstring is a format that can be sent to any system. In my case I want to send it to an SQLite database. However, SQLite does not support images. the closest thing to it is a blob type. A blog type accepts a bunch of bytes. While this is good, it might not always suit your purposes.
If you do not want to use a blob type, you can use the text type. In the following blog post I will detail how to convert an uiimage to nsdata to nsstring. Then how to turn that nsstring back to data then back to uiimage.
UIImage *originalImage = ...; //get image from somewhere. a path or an iphoto library.
NSData *originalData = UIImagePNGRepresentation(originalImage);
NSString *originalString = [originalData base64EncodedStringWithOptions:NSDataBase64Encoding64CharacterLineLength];
//Now that you have the data in a string format you can pass it around. In my case I stored it in my SQLite database. Now if I want to retrieve it I need to convert it back.
NSData *decodedData = [[NSData alloc] initWithBase64EncodedString:originalString options:NSDataBase64DecodingIgnoreUnknownCharacters];
UIImage *decodedImage = [UIImage imageWithData:decodedData];
-------------------
There is only one decoder option: "NSDataBase64DecodingIgnoreUnknownCharacters"
But there are four encoder options. In the example above I used "NSDataBase64Encoding64CharacterLineLength"
but there are 3 others. What are the differences and why would you use them?
- NSDataBase64Encoding64CharacterLineLength
- Sets the maximum line length to 64 characters, after which a line ending is inserted.
- NSDataBase64Encoding76CharacterLineLength
- Sets the maximum line Length to 76 characters, after which a line ending is inserted.
- NSDataBase64EncodingEndLineWithCarriageReturn
- When a maximum line length is set, specify that the line ending to insert should include a carriage return
- NSDataBase64EncodingEndLineWithLineFeed
- When a maximum line length is set, specify that the line ending to insert should include a line feed.
Wednesday, June 11, 2014
Xvolve programming assignment
You are given two lines.
the first line tells you how many numbers (N) are in the array, the second tells you the difference(K) that you must find.
The second line give you a string of numbers.
Your goal is to count the number of numbers that have a difference (K).
input
5 2
1 5 3 4 2
output
3
in the above input N is 5 and K is 2. I must find all numbers that have a difference of 2.
There are two ways to do this. The brute fore way and the better way. The brute force way does it the way that you would expect. Create an array of numbers and for each number compare it to every other number until you get to the end. then you increment to the next number lined up and compare that to every other number until you reach the end. The running time of this algorithm is O(n^2). It gets the job done but it does too many comparisons.
the brute force method is called match1.
The better method is called match2.
First it sorts the array of numbers. We start at the left most index i and compare it to index j. We will compare it until the values of j are greater than the expected diff. If it is less than K we increment j to the next. if it is the same as K then we increment numberOfMatches and then increment J.
This actuall results in much less comparisons.
look at my test cases:
After the dollar sign we the I show the number of comparisons, the number of matchs for brute force, the next two are the better method. Observe the difference.
I think the better method is O(nlogn)
Code is below
#include <stdio.h>
#include <stdlib.h>
int compare(const void *a, const void *b) {
return *(int*)a - *(int*)b;
}
int match1(int *arrOfNum, int len, int diff) {
int i,j;
int numMatches=0;
int numComparisons = 0;
for(i = 0; i < len-1; ++i) {
for(j = i + 1; j < len; ++j) {
//printf("%d - %d\n", arrOfNum[i], arrOfNum[j]);
numComparisons++;
if(abs(arrOfNum[i] - arrOfNum[j]) == diff) {
numMatches++;
}
}
}
printf("(%d)\n", numComparisons);
return numMatches;
}
int match2(int *arrOfNum, int len, int diff) {
qsort(arrOfNum, len, sizeof(int), compare);
int i = 0, j = i + 1;
int *a = arrOfNum;
int numMatches = 0;
int numComparisons = 0;
for(; i < len-1;++i) {
for(j = i + 1; j < len;++j) {
//printf("%d - %d\n", arrOfNum[i], arrOfNum[j]);
numComparisons++;
if(a[i] + diff > a[j]) {continue;}
else if(a[i] + diff == a[j]){
numMatches++;
} else {
break;
}
}
}
printf("(%d)\n", numComparisons);
return numMatches;
}
int main(int argc, char **argv) {
char cN[10];
char cK[10];
char number[20];
FILE *f = fopen(argv[1], "r");
if (!f){ //error
return -1;
}
fscanf(f, "%s %s", cN, cK);
int N = (int)strtol(cN, NULL, 10);
int K = (int)strtol(cK, NULL, 10);
int numMatches = 0;
int arrOfNum[100000];
int i = 0;
while(1 == fscanf(f, "%s", number)) {
arrOfNum[i] = (int)strtol(number, NULL, 10);
++i;
}
numMatches = match1(arrOfNum, N, K);
printf("%d\n", numMatches);
numMatches = match2(arrOfNum, N, K);
printf("%d\n", numMatches);
return 0;
}
the first line tells you how many numbers (N) are in the array, the second tells you the difference(K) that you must find.
The second line give you a string of numbers.
Your goal is to count the number of numbers that have a difference (K).
input
5 2
1 5 3 4 2
output
3
in the above input N is 5 and K is 2. I must find all numbers that have a difference of 2.
There are two ways to do this. The brute fore way and the better way. The brute force way does it the way that you would expect. Create an array of numbers and for each number compare it to every other number until you get to the end. then you increment to the next number lined up and compare that to every other number until you reach the end. The running time of this algorithm is O(n^2). It gets the job done but it does too many comparisons.
the brute force method is called match1.
The better method is called match2.
First it sorts the array of numbers. We start at the left most index i and compare it to index j. We will compare it until the values of j are greater than the expected diff. If it is less than K we increment j to the next. if it is the same as K then we increment numberOfMatches and then increment J.
This actuall results in much less comparisons.
look at my test cases:
$
(10)
3
(9)
3
$
(31996000)
0
(7999)
0
$
(7998000)
0
(3999)
0
$
(45)
0
(9)
0
After the dollar sign we the I show the number of comparisons, the number of matchs for brute force, the next two are the better method. Observe the difference.
I think the better method is O(nlogn)
Code is below
#include <stdio.h>
#include <stdlib.h>
int compare(const void *a, const void *b) {
return *(int*)a - *(int*)b;
}
int match1(int *arrOfNum, int len, int diff) {
int i,j;
int numMatches=0;
int numComparisons = 0;
for(i = 0; i < len-1; ++i) {
for(j = i + 1; j < len; ++j) {
//printf("%d - %d\n", arrOfNum[i], arrOfNum[j]);
numComparisons++;
if(abs(arrOfNum[i] - arrOfNum[j]) == diff) {
numMatches++;
}
}
}
printf("(%d)\n", numComparisons);
return numMatches;
}
int match2(int *arrOfNum, int len, int diff) {
qsort(arrOfNum, len, sizeof(int), compare);
int i = 0, j = i + 1;
int *a = arrOfNum;
int numMatches = 0;
int numComparisons = 0;
for(; i < len-1;++i) {
for(j = i + 1; j < len;++j) {
//printf("%d - %d\n", arrOfNum[i], arrOfNum[j]);
numComparisons++;
if(a[i] + diff > a[j]) {continue;}
else if(a[i] + diff == a[j]){
numMatches++;
} else {
break;
}
}
}
printf("(%d)\n", numComparisons);
return numMatches;
}
int main(int argc, char **argv) {
char cN[10];
char cK[10];
char number[20];
FILE *f = fopen(argv[1], "r");
if (!f){ //error
return -1;
}
fscanf(f, "%s %s", cN, cK);
int N = (int)strtol(cN, NULL, 10);
int K = (int)strtol(cK, NULL, 10);
int numMatches = 0;
int arrOfNum[100000];
int i = 0;
while(1 == fscanf(f, "%s", number)) {
arrOfNum[i] = (int)strtol(number, NULL, 10);
++i;
}
numMatches = match1(arrOfNum, N, K);
printf("%d\n", numMatches);
numMatches = match2(arrOfNum, N, K);
printf("%d\n", numMatches);
return 0;
}
Wednesday, September 11, 2013
Reverse a singly linked list
static void _inPlaceRev( Node *cursor, Node *prev) {
if(!cursor) {
return;
}
_inPlaceRev(head, tail, cursor->next, cursor);
cursor->next = prev;
}
static void inPlaceRev(LinkedList * _my) {
_inPlaceRev(_my->head, NULL);
_my->head ^= _my->tail;
_my->tail ^= _my->head;
_my->head ^= _my->tail;
}
Monday, May 13, 2013
Object Oriented C
Since C is the mother of all the object oriented languages such as Objective c, c++, java, c#, and everything else, then C should have had SOME ability to be object oriented.
Object orientation is really, a pattern that helps reduce low level problems, such as memory management and encapsulation. So, before Object oriented patterns became native, people in C would make the pattern. I have made something that resembles that pattern.
The pattern includes:
1) data encapsulation
2) public member functions.
Object Oriented Linked List
Thursday, March 14, 2013
Send STDERR to terminal output. STDOUT to file
How to send STDERR to the terminal output and the STDOUT to a file.
Normally the STDOUT and STDERR are both sent to the terminal output.
To split them up we can use ">" and "2>" for STDOUT and STDERR respectively.
generic example
( cool_prog > cool_file ) 2>&1
**note, the parentheses are required or else it will not work**
The Explanation:
cool_prog will attempt to send thing into STDOUT. The ">" will send it into cool_file.
cool_prog will attempt to send thing into STDERR. The "2>&1" will send it to terminal output.
">&" should achieve the same effect as "2>&1"
To find more look at these links
http://www.macobserver.com/tips/macosxcl101/2002/20020607.shtml
http://www.tldp.org/LDP/abs/html/io-redirection.html
Friday, January 18, 2013
How to use cellular ram from micron M45W8MW16
Purpose/Goal/Desire:
To use the micron cellular ram as if it was a block ram.
A cpu is useless without ram. My original approach was to use
block ram to create a ROM to store the main program files. and then
to use block ram for general purpose ram to store the stack and heap stuff.
When it came down to synthesis, I found that I only had enough block ram
for the rom. I had two options, buy a bigger machine, or use micron's block ram.
It took a large sum of time to figure out how to use it, but in the end it paid off.
Remember that this is a guide in using asynchronous mode. Its slower, but it makes everything
more homogenous. And since I'm using it as a ram, I have no idea where the cpu is going to set/get the data.
Stuff that you need to make it work:
Gotchas
my FSM
T : timer 10 ns
//These pins are used to talk to the celular ram (memory_interface <--> cellular_ram);
addr_o : out std_logic_vector( addr_width-1 downto 0);
clk_o : out std_logic;
addr_valid_o :out std_logic;
cntl_reg_enable_o : out std_logic;
chip_enable_o : out std_logic;
output_enable_o : out std_logic;
write_en_o : out std_logic;
lower_byte_en_o : out std_logic;
upper_byte_en_o : out std_logic;
data_io : inout std_logic_vector( data_width-1 downto 0);
wait_i : in std_logic;
//These are the pins used to help interface the memory as if it were a block ram ( some module <--> memory_interface);
addr_i : in std_logic_vector (addr_width-1 downto 0);
we_i : in std_logic ;
data_i : in std_logic_vector (data_width-1 downto 0);
data_o : out std_logic_vector (data_width-1 downto 0);
clk_i : in std_logic;
go_i : in std_logic //top module should set this to 0. when ready to use, set to 1 for one cycle (max 90 ns) then bring down. when go_i is high it will read or write otherwise it will be idle.;
View this high level pic to see where everything falls in place
Code: the stuff you probably just wanna take and play with right out of the box and probably the only thing you care about
memory interface
component used to interact with the memory interface
The two links above are synthesis able. I linked them together in a wrapper file, loaded them on to the FPGA and crossed my fingers. The first link goes to the source code for the memory interface. It lets you use the memory as if it was a block ram. But be warned....you may only read/write every 100ns. Any slower will cause unexpected data. Going slower is pretty much acceptable. Oh yeah, remember to toggle the go_i input when you want to read/write.
the second link takes you to what looks like a massively long entity. In actuality it has several architectures. Each architecture has a different test. One of them writes to 16k memory arrays one after the other, then reads them one after another. Another test jumps really far to write and then jumps to read each of them.
To use the micron cellular ram as if it was a block ram.
A cpu is useless without ram. My original approach was to use
block ram to create a ROM to store the main program files. and then
to use block ram for general purpose ram to store the stack and heap stuff.
When it came down to synthesis, I found that I only had enough block ram
for the rom. I had two options, buy a bigger machine, or use micron's block ram.
It took a large sum of time to figure out how to use it, but in the end it paid off.
Remember that this is a guide in using asynchronous mode. Its slower, but it makes everything
more homogenous. And since I'm using it as a ram, I have no idea where the cpu is going to set/get the data.
Stuff that you need to make it work:
- spec sheet
- They added an extra T to the name, making it harder to find
- Spartan 6 on nexus 3
- it has enough bram for a 32kx16 rom. If you have a bigger board then you probably don't need to use the micron cellular ram.
- A guide for asynchronous mode
- pay attention to only slides 13,14, 21, and 22
- xilinx (i used version 14, but other versions should still work)
Gotchas
- You gotta let the device power on before you can use it. see init state in the FSM
- The specs say that you can do async read and write in 70 ns. True, but once you add the commands to start the device up you get closer to 100 ns.
- using tristate buffers on the bidirectional dq bus is a must.
- The specs brag about the memory running at 80mhz, but that is for burst/page mode which are much harder to use. Async mode will get you 10mhz.
my FSM
T : timer 10 ns
//These pins are used to talk to the celular ram (memory_interface <--> cellular_ram);
addr_o : out std_logic_vector( addr_width-1 downto 0);
clk_o : out std_logic;
addr_valid_o :out std_logic;
cntl_reg_enable_o : out std_logic;
chip_enable_o : out std_logic;
output_enable_o : out std_logic;
write_en_o : out std_logic;
lower_byte_en_o : out std_logic;
upper_byte_en_o : out std_logic;
data_io : inout std_logic_vector( data_width-1 downto 0);
wait_i : in std_logic;
//These are the pins used to help interface the memory as if it were a block ram ( some module <--> memory_interface);
addr_i : in std_logic_vector (addr_width-1 downto 0);
we_i : in std_logic ;
data_i : in std_logic_vector (data_width-1 downto 0);
data_o : out std_logic_vector (data_width-1 downto 0);
clk_i : in std_logic;
go_i : in std_logic //top module should set this to 0. when ready to use, set to 1 for one cycle (max 90 ns) then bring down. when go_i is high it will read or write otherwise it will be idle.;
View this high level pic to see where everything falls in place
Code: the stuff you probably just wanna take and play with right out of the box and probably the only thing you care about
memory interface
component used to interact with the memory interface
The two links above are synthesis able. I linked them together in a wrapper file, loaded them on to the FPGA and crossed my fingers. The first link goes to the source code for the memory interface. It lets you use the memory as if it was a block ram. But be warned....you may only read/write every 100ns. Any slower will cause unexpected data. Going slower is pretty much acceptable. Oh yeah, remember to toggle the go_i input when you want to read/write.
the second link takes you to what looks like a massively long entity. In actuality it has several architectures. Each architecture has a different test. One of them writes to 16k memory arrays one after the other, then reads them one after another. Another test jumps really far to write and then jumps to read each of them.
Tuesday, October 30, 2012
vhdl random number generator for test benches
LIBRARY ieee;
USE ieee.std_logic_1164.ALL;
USE ieee.math_real.ALL; -- for UNIFORM, TRUNC functions
USE ieee.numeric_std.ALL;
tb: process
VARIABLE seed1, seed2: positive; -- Seed values for random generator
VARIABLE rand: real; -- Random real-number value in range 0 to 1.0
VARIABLE int_rand: integer; -- Random integer value in range 0..4095
variable time_var1, time_var2: time ;
begin
uniform(seed1, seed2,rand); -- generate random number
int_rand := INTEGER(trunc(rand*4096.0)); -- rescale to 0..4069, find integer part
int_rand := to_integer((to_unsigned(int_rand, 14)) );
time_var2 := (10 ms + (int_rand*1 us)); --save random time n a variable
rand_clock2 <= time_var2; --Save time to a signal so I can see it in waveform
wait for time_var2; --wait for duration random time
end process;
some explaination.....
the uniform function generates a psudo random number. It is a "real" number so once it is generated the value must be truncated and then converted into an integer.
In this example I chose to turn that integer into a value that would vary the time delays.
References
Monday, September 3, 2012
Verilog Arrays
2d arrays always confuse me, so to save me some headache I'll post what I know about verilog arrays here for reference.
------------------------------------------------------------------------------------
reg [7:0] w; // bus of width 8. aka std_logic_vector(7 downto 0);
(picture)
[7][6][5][4][3][2][1][0]
------------------------------------------------------------------------------------
reg arr [0:3]; // array of size 4 with 1 bit elements. aka array (0 to 3) of std_logic;
(picture)
[0]
[1]
[2]
[3]
------------------------------------------------------------------------------------
reg [7:0] arr [0:3];// 2d array. aka array (0 to 3) of std_logic_vector(7 downto 0);
(picture)
key
(...) -- index
[...] -- stored value
(7)(6)(5)(4)(3)(2)(1)(0)
[0][1][2][3][4][5][6][7](0)
[8][9][a][b][c][d][e][f](1)
[g][h][i][j][k][l][m][n](2)
[o][p][q][r][s][t][u][v](3)
to access the elements in the array you need to use the operator []
arr[2]; // will give access to row 2. aka return an 8 bit word.
// will return an value of "ghijklmn"
arr[0][3:2];// will go to row 0 then access columns 3 to 2
// will return a value of "45"
arr[row][column];
//notes you can slice a column in to different sizes, but you can only access one row at a time.
------------------------------------------------------------------------------------
reg [7:0] w; // bus of width 8. aka std_logic_vector(7 downto 0);
(picture)
[7][6][5][4][3][2][1][0]
------------------------------------------------------------------------------------
reg arr [0:3]; // array of size 4 with 1 bit elements. aka array (0 to 3) of std_logic;
(picture)
[0]
[1]
[2]
[3]
------------------------------------------------------------------------------------
reg [7:0] arr [0:3];// 2d array. aka array (0 to 3) of std_logic_vector(7 downto 0);
(picture)
key
(...) -- index
[...] -- stored value
(7)(6)(5)(4)(3)(2)(1)(0)
[0][1][2][3][4][5][6][7](0)
[8][9][a][b][c][d][e][f](1)
[g][h][i][j][k][l][m][n](2)
[o][p][q][r][s][t][u][v](3)
to access the elements in the array you need to use the operator []
arr[2]; // will give access to row 2. aka return an 8 bit word.
// will return an value of "ghijklmn"
arr[0][3:2];// will go to row 0 then access columns 3 to 2
// will return a value of "45"
arr[row][column];
//notes you can slice a column in to different sizes, but you can only access one row at a time.
Verilog vs VHDL
UCR started me off with VHDL. It was definately a struggle to learn how to avoid all the little errors. The errors were of course my own fault for not realizing the nature of how hardware logic works. Software does things differently then hardware does it, and I struggled with vhdl until I had learned the differences. In the end, I developed a fondness for the HDL.
After graduation, it was up to me to decide my education. My self taught education. Verilog was the popular HDL in america and it would be a good idea to learn it since that is where everyone is at. I gave it a shot and to my surprise, it was vastly more easy. It probably has more to do with my experience with vhdl then the simplicity of the language. I had already understood hardware so it was easy to learn the new language.
The two languages are essentially two different interfaces with the same thing.
The basic components like AND, REG, and COUNTER were finished with ease. But I discovered a problem when I tried synthesising the counter.
Here is a snippet of code
==========
...
wire [WIDTH-1:0] reg2adder_w, adder2reg_w;
sreg_gen #( .WIDTH(WIDTH))
sreg(
.clock(clock), .reset(reset), .en(enable),
.data_i( adder2reg_w),
.data_o( reg2adder)
);
assign count = reg2adder;
...
=====
end snippit
look at the snippit and tell me if you see a problem.......got it? there is no wire named"reg2adder". It was a typo and verilog responds by giving me warnings. It responds by implicitly creating a wire called "reg2adder" of bitwidth 1. So it gives me warnings telling me that the data_o is 32 bits and it is trying to shove it into reg2adder which is 1 bits. This makes 31 of data_o's bits unconnected!
In VHDL, this would have turned out differently. In VHDL it would have simply said something along the lines of "ERROR:reg2adder not declared". Thats a much easier explanation then the warning I had recieved for verilog .
I've heard that verilog tends to sweep errors under the rug, but I didn't think it would make a mistake on something so simple.....
So the moral of the story is to make sure that you are using the right wire names cause apparently, verilog won't catch it for you.
VHDL one.... Verilog zero....
Saturday, August 18, 2012
Using screen to send serial communication rs232 at 9600 baud rate
A few weeks ago, I found a great method for sending and receiving serial data.
When I did the UART lab in school we used cute com in order to send and receive a byte of information. for example, if I entered "Hello" in to the cute com, it would send something through the usb. The usb would enter the nexus 3 spartan6 board. some magic would happen and then it would send back the message through the usb and into the pc. then cutecom would show"Hello" again.
ie "HelloHello"
The problem was that I was using a mac and at the time I had no idea how to do something like cute com. I know about the existence of mini com but I did not want to download it. In the back of my mind I thought that this would be a great opportunity for me to make my own "mini com", but the question what how? I had many fruitless googling until I stumbled upon "screen".
Apparently "screen" could be used instead of "mini com" . This was great news! I'm not going to go into the technical details of how I interfaced my fpga with my mac book pro (10.7) because I had covered that in a past post.
Question....How to use screen? It isn't hard. After you plug it in you type this into the terminal without the quotes.
"screen <usbserial_com> <baud_rate>"
in my case the usbserial_com was "/dev/tty.usbserial-A700h2To"
and my baud rate "9600"
ie.
"screen /dev/tty.usbserial-A700h2To 9600"
How do I test if it works?
I pulled out one of my old UARTio labs from the past. All it did was receive and transmit. It was an unfinished project where I was suppose to add keyboard functionality to it, but I never got around to it. Luckly, my procrastination turned out for the better, cause now I could simply compile what I had without having to change anything.
I compiled it, and programmed the fpga. flipped the switches.
I ran the screen command that I mentioned above.
at first it looked like an empty terminal.
I typed "a" and I recieved an "a". I turned off the fpga and typed "a" again. nothing happened.
So the uartio was working correctly. I type something in, it goes to the fpga then pops back to the terminal. SWEET.
ok, what about a more realistic solution? eventually I would write a program that would read in an image (i.e. bmp) and send some info through the usb and write somewhere on the fpga memory.
So at first i thought I could write a c++ program that would run "screen"
But as it turns out, most programs wouldn't do that.
Eventually I found this neat site from arduino. It was meant for serial compunication with an arduino, but oh well, same difference.
http://todbot.com/arduino/host/arduino-serial/arduino-serial.c
Here is a link to more languages.
http://www.arduino.cc/playground/Main/InterfacingWithSoftware
As of now, I'm using the "C" version. Reason being that it is useful for osx/windows/linux.
The only problem is that I haven't quite figured out how it works. After tracing it with my eyes, I tried distilling the most essential parts so that I could make my own dedicated program. I failed. for now, But eventually I'll get it.
So then I tried using the Arduino C code as is and it actually worked.
ie ./a.out -b 9600 -p /dev/tty.usbserial-A700h2To -s 3; //actually sends the ascii version of 3.
Oh yeah, the data I send to the fpga shows up on the 8 led's so I can verify what is being sent.
TMR I will go through the program more carefully and trace its path. I WILL find out how to write my own.
Friday, August 17, 2012
bram timing
I went ahead and played with Isim because I wanted to find out how long it would take for a value to be written to the bram data.
So I opened the ip generator and selected block ram.
16 wide and 16 tall.
I hooked up the DCM and tested it to see what would happen.
oh yeah, the DCM needs some special configurations. Instead of going blah blah, I'll just copy and past it right here
-------
DCM_CLKGEN_inst : DCM_CLKGEN
generic map (
CLKFXDV_DIVIDE => 2, -- CLKFXDV divide value (2, 4, 8, 16, 32)
CLKFX_DIVIDE => 1, -- Divide value - D - (1-256)
CLKFX_MD_MAX => 0.0, -- Specify maximum M/D ratio for timing anlysis
CLKFX_MULTIPLY => 256, -- Multiply value - M - (2-256)
CLKIN_PERIOD => 0.0, -- Input clock period specified in nS
SPREAD_SPECTRUM => "NONE", -- Spread Spectrum mode "NONE", "CENTER_LOW_SPREAD", "CENTER_HIGH_SPREAD",
-- "VIDEO_LINK_M0", "VIDEO_LINK_M1" or "VIDEO_LINK_M2"
STARTUP_WAIT => FALSE -- Delay config DONE until DCM_CLKGEN LOCKED (TRUE/FALSE)
)
port map (
CLKFX => CLKFX, -- 1-bit output: Generated clock output
CLKFX180 => CLKFX180, -- 1-bit output: Generated clock output 180 degree out of phase from CLKFX.
CLKFXDV => CLKFXDV, -- 1-bit output: Divided clock output
LOCKED => open, -- 1-bit output: Locked output
PROGDONE => open, -- 1-bit output: Active high output to indicate the successful re-programming
STATUS => open, -- 2-bit output: DCM_CLKGEN status
CLKIN => clock, -- 1-bit input: Input clock
FREEZEDCM => '0', -- 1-bit input: Prevents frequency adjustments to input clock
PROGCLK => open, -- 1-bit input: Clock input for M/D reconfiguration
PROGDATA => open, -- 1-bit input: Serial data input for M/D reconfiguration
PROGEN => open, -- 1-bit input: Active high program enable
RST => '0' -- 1-bit input: Reset input pin
);
-------
ok, to make a long story short, the multiplied clock signal shall be called "clkfx"
The not clock is called "clkfx180".
I write using the rising edge of clkfx180. I read using the rising edge of "clkfx"
This is mainly for the VGA screen. The timer needs to be in synce with read.
So anyways, how long DOES it take to write to the memory?
well, when I ramp the multiplier to 256, it takes 0.000144 us.
The down side was that clkfx must tick 5 times.
mult | time(ns) | clkfx ticks
256 | 0.144 | 5
128 | 0.183 | 3
64 | 0.183 | 2
32 | 0.339 | 2
16 | 0.724 |2
it seams like 64 multiplier seems to be the best choice. I just have to make sure that I hold the data value and the write enable needs to be held for 2 ticks.
lets say it takes 0.2 ns to write. How long will it take to clear the pixel mem?
The pixel mem has 320*240 = 76800 addresses.
0.2ns*76800 = 15360ns
--
perhaps I want the print to clear ratio to be 999:1
0.0153 sec or 15 ms will be spend printing .
this would have ~ 60hz period of writing and clearning.
Hopefully with this config, I would be able to get rid of the flicker the plagues my project.
-----
The duty is low, it shall work for the duration of 15360ns.
the duty will be high for the durations of 15 ms.
good exercices to do
This is for a computer architechture classes and I found their labs quite useful for practicing
http://students.cse.tamu.edu/wanglei/csce350/handout/lab6.html
http://students.cse.tamu.edu/wanglei/csce350/handout/lab6.html
Sunday, August 12, 2012
Latch verse flip-flop
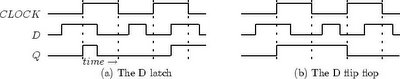
It appears that in a latch, the clock is being used as an enable line which dictates WHEN D should set Q.
ie
Q <= D when enable = '1' else Q; --latch
It appears that a flip flop, uses the rising edge of the clock to write. D will set Q when it sees a rising edge.
ie
Q <= D when clock = '1' and clock'event else Q; --flip-flop
---------
The below is Reblogged from here
Many experienced engineers are clueless about the differences between a "Latch" and a "Flip Flop", and i have seen people using the terms synonymously. I feel that the right use of terminology is very critical in conveying the message more clearly.
I m sure the timing diagrams below is the best way of explanation.
ie
Q <= D when enable = '1' else Q; --latch
It appears that a flip flop, uses the rising edge of the clock to write. D will set Q when it sees a rising edge.
ie
Q <= D when clock = '1' and clock'event else Q; --flip-flop
---------
The below is Reblogged from here
I m sure the timing diagrams below is the best way of explanation.

Create logic gates out of muxes
I have created the AND, OR, NOT, gates using a multiplexer. With the power of these three you can make all the other logic gates.


Subscribe to:
Posts (Atom)